
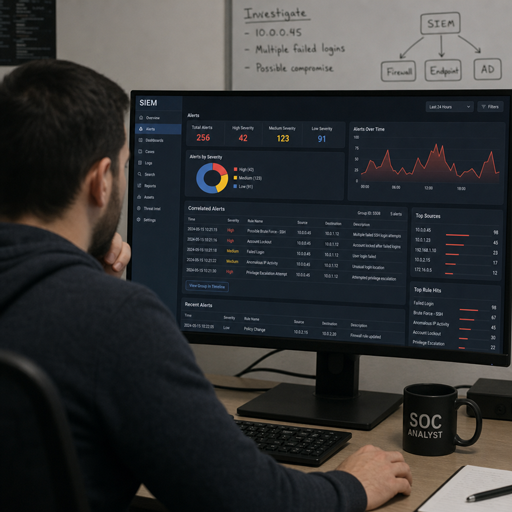
A SIEM becomes far more valuable when it can connect related events and turn scattered signals into meaningful alerts. Writing custom correlation rules for SIEM helps security teams detect activity that default content may miss, especially when the environment has unique systems, workflows, identities, and risk patterns. The goal is not to create more noise; it is to create better logic that points analysts toward behavior worth investigating.
What makes a SIEM correlation rule useful?
A useful SIEM correlation rule identifies a meaningful pattern across events, applies enough context to reduce false positives, and produces an alert that an analyst can understand and act on. It should answer three practical questions: what happened, why it matters, and what should be checked next. If a rule only matches isolated events without context, it may be a simple detection, but it is not taking full advantage of SIEM event correlation.
Strong rules usually reflect real risk in your environment. For example, a failed login from a normal user may not matter on its own, but repeated failures followed by a successful login from an unusual location could indicate credential compromise. Likewise, a privilege change is expected in some administrative workflows, but it becomes more concerning when it happens shortly after suspicious authentication activity.
Good SIEM correlation rules also fit the way your team investigates. An alert should include the key fields an analyst needs, such as user, host, source IP, destination, event category, time window, and related activity. The best custom rules make the first few minutes of triage faster, not harder.
Start with the behavior, not the tool
Before writing rule logic, define the behavior you want to detect in plain language. This keeps the rule tied to a security outcome instead of a platform feature. A clear behavioral statement might be: “Detect a user account that experiences multiple failed logins and then successfully authenticates from the same source within a short time window.”
That statement can then be translated into fields, event types, thresholds, and conditions. Starting this way prevents rules from becoming overly broad, overly technical, or disconnected from actual risk. It also makes the rule easier to review with stakeholders who may not know the SIEM query language.
A practical rule plan should include:
- Detection objective: The threat, misuse, or risky behavior the rule is intended to identify.
- Required data sources: Logs from identity providers, endpoints, firewalls, cloud platforms, applications, or network tools.
- Key fields: Usernames, device names, IP addresses, process names, event IDs, geolocation, ports, or resource names.
- Time window: The period in which related events must occur to be considered connected.
- Thresholds: Counts, frequency, rarity, or sequence requirements that separate suspicious behavior from normal activity.
- Expected response: What an analyst should verify when the alert fires.
This planning step may feel slower at first, but it usually saves time during tuning. It also helps create consistent documentation for future rule owners.
Core components of custom correlation rules for SIEM
Most custom correlation rules for SIEM combine several building blocks. The exact syntax depends on the platform, but the underlying concepts are similar across many SIEM tools. Understanding these components makes it easier to build detections that are reliable, readable, and maintainable.
Event selection
Event selection defines which logs are eligible for the rule. This may include authentication events, endpoint alerts, DNS queries, firewall denies, cloud control plane activity, or application audit logs. If event selection is too broad, the rule may become noisy or expensive to run. If it is too narrow, it may miss important variations of the same behavior.
Start with the most authoritative log source for the behavior. For identity activity, that may be your identity provider rather than individual application logs. For endpoint behavior, endpoint detection telemetry may be more useful than basic operating system logs. Use supporting logs later to enrich or confirm the pattern.
Conditions and thresholds
Conditions define what must be true for the rule to match. Thresholds define how much activity is enough to matter. A rule might require five failed logins within ten minutes, a new administrative role assignment, or outbound connections to multiple rare destinations.
Thresholds should reflect your environment, not someone else’s template. A normal threshold for a small organization may be useless in a large enterprise, and a rule that works for office users may not work for service accounts. When possible, review historical data before choosing numbers.
Time windows and sequencing
SIEM event correlation is often about timing. Events that are harmless in isolation can become suspicious when they occur in a specific order. A sequence such as phishing email received, user login from unusual location, mailbox rule created, and data downloaded is more valuable than any single event alone.
Time windows should be long enough to capture realistic attacker behavior but short enough to preserve relevance. If the window is too short, the rule may miss slow activity. If it is too long, unrelated events may be incorrectly linked.
Grouping and entity logic
Grouping tells the SIEM which events belong together. Common grouping keys include user, host, source IP, destination IP, cloud account, process, or application. Choosing the wrong grouping key can make a rule misleading.
For example, grouping failed logins by source IP may highlight a password spraying source, while grouping by user may highlight a targeted account. Both can be useful, but they answer different questions. Be intentional about the entity you want the analyst to investigate.
How do you reduce false positives without weakening detection?
You reduce false positives by adding context, exclusions, and better thresholds while preserving the suspicious pattern the rule was designed to catch. The key is to tune the rule against known benign activity without creating broad allowlists that hide real threats. Every exception should have a reason, an owner, and a review date.
False positives are not just annoying; they can reduce trust in the SIEM. When analysts see too many low-value alerts, they may miss the ones that matter. Tuning is therefore part of detection engineering, not an afterthought.
Useful tuning methods include:
- Baseline normal activity. Look at recent historical logs to understand common users, systems, locations, and processes.
- Separate human and service accounts. Service accounts often behave differently and may need dedicated rules or thresholds.
- Use asset and identity context. A failed login to a low-risk test system is different from the same pattern against a domain administrator account.
- Add suppression carefully. Suppress repetitive benign alerts, but avoid broad exclusions such as entire networks unless truly justified.
- Score risk instead of firing immediately. Some behaviors are better treated as risk signals that contribute to a higher-confidence alert.
- Review closed investigations. Analyst feedback is one of the best sources for improving rule quality.
Tuning should not remove the original detection intent. If a rule becomes so narrow that it only catches one known scenario, it may fail against a slightly different attack path.
Examples of practical SIEM correlation rules
The following examples are intentionally generic because each SIEM platform uses different syntax. They can, however, help shape your own logic and documentation.
Failed logins followed by success
This rule detects multiple failed authentication attempts followed by a successful login for the same account within a defined period. It can help identify brute force attempts, password guessing, or compromised credentials. To improve quality, enrich the alert with source location, device reputation, user risk, and whether multi-factor authentication was used.
Privilege change after unusual login
This rule connects an unusual authentication event with a sensitive administrative action. For example, a user logs in from an unfamiliar source and then receives elevated privileges or modifies access policies. This pattern can be more meaningful than alerting on every privilege change.
New process and network connection
Endpoint and network logs can be correlated to identify a newly observed process that initiates outbound connections. The rule becomes stronger when the process path, parent process, command line, destination reputation, and device role are included. This can help analysts distinguish expected software behavior from suspicious execution.
Cloud configuration change from risky context
Cloud environments generate many administrative events. A custom rule can look for sensitive changes, such as disabling logging, opening access, modifying identity policies, or changing security controls, especially when paired with unusual authentication context. These detections are most useful when mapped to the cloud services and permissions your organization actually uses.
Rule documentation matters as much as rule logic
A rule that only one person understands is fragile. Documentation helps future analysts, engineers, and auditors understand why the rule exists and how it should be handled. It also makes maintenance easier when log sources change or business processes evolve.
A simple documentation template can include:
- Rule name: Clear, specific, and easy to search.
- Purpose: The behavior or risk being detected.
- Data sources: Required logs and any dependencies.
- Logic summary: A plain-language explanation of the correlation.
- Severity rationale: Why the alert is low, medium, high, or critical.
- Known false positives: Expected benign scenarios and approved exclusions.
- Triage steps: What analysts should verify first.
- Owner: The person or team responsible for review and updates.
- Last reviewed: A date or review cycle to prevent stale content.
This documentation does not need to be long. It needs to be accurate, findable, and useful during an investigation.
Testing and tuning before production
Before enabling a rule in production alerting, test it against historical data. This helps estimate alert volume, identify obvious false positives, and confirm that the rule actually matches the intended behavior. If possible, run the rule silently at first so you can observe results without overwhelming the queue.
Testing should include both positive and negative validation. Positive validation confirms that the rule catches known or simulated suspicious activity. Negative validation confirms that normal business activity does not constantly trigger alerts. If you cannot safely simulate an event, use controlled test data or past incidents where available.
After deployment, monitor the rule’s performance. Track whether alerts are investigated, closed as benign, escalated, or linked to incidents. A rule that never fires may still be valuable for rare high-impact scenarios, but a rule that fires constantly without action probably needs refinement.
Maintaining SIEM correlation rules over time
SIEM correlation rules are not “set and forget” controls. Business systems change, attackers adapt, cloud services evolve, and log formats shift. A rule that worked well last year may become noisy or blind if the underlying data changes.
Build maintenance into your detection program. Review high-volume rules frequently, revisit critical rules after major infrastructure changes, and retire rules that no longer serve a clear purpose. Version control, peer review, and change notes can make custom rule management more reliable.
It also helps to group rules by use case, such as identity, endpoint, network, cloud, data access, and email security. This makes coverage easier to assess and reduces duplicated logic. Over time, your rule library should become a curated detection asset rather than a pile of queries.
Key takeaways for better SIEM event correlation
Writing effective SIEM correlation rules is part technical work and part security judgment. The logic must be precise enough to find meaningful patterns, but flexible enough to reflect how people and systems actually behave.
Keep these principles in mind:
- Start with a clear behavior or risk, then translate it into SIEM logic.
- Use reliable data sources and confirm that required fields are consistently populated.
- Correlate events by time, sequence, and entity instead of alerting on isolated activity.
- Tune with context, not broad exclusions that create blind spots.
- Document every rule so analysts know what the alert means and what to do next.
- Review rules regularly as your environment and threat model change.
Custom correlation rules for SIEM are most valuable when they improve clarity. They should help the security team see the story behind the logs, prioritize the right activity, and move from raw events to confident investigation faster.
