
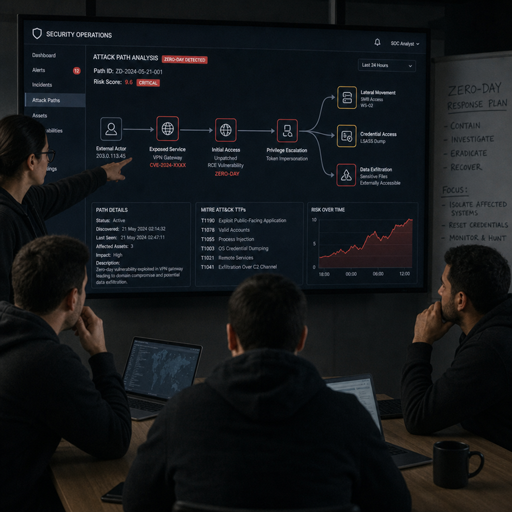
Zero-day vulnerabilities are security flaws that are unknown to the vendor, unpatched in the wild, or newly disclosed before defenders have a reliable fix. Because there may be no patch available at first, mitigation depends on layered defenses: reducing exposure, detecting suspicious behavior, limiting blast radius, and moving quickly when new intelligence appears. This guide explains how zero-day risk works and how to build a practical program that strengthens vulnerability management, threat detection, patch management, and incident response.
What are zero-day vulnerabilities?
Zero-day vulnerabilities are software, firmware, hardware, or configuration flaws that attackers can exploit before the affected organization has had “zero days” to prepare a formal fix. In practical terms, a zero-day may be unknown to the vendor, known only to attackers, or publicly disclosed before a patch is released. The danger is not just the flaw itself, but the time gap between discovery, detection, remediation, and broad defensive coverage.
A zero-day exploit is the method used to take advantage of the vulnerability. A zero-day attack is the actual intrusion or malicious campaign using that exploit. Those distinctions matter because mitigation can happen at different points: you may not be able to remove the vulnerability immediately, but you can still block exploit paths, reduce privileges, detect abnormal behavior, and contain compromised assets.
Zero-days often gain attention because they can bypass traditional controls that depend on known signatures. Still, they are not magic. Many successful attacks rely on familiar weaknesses around exposed services, overprivileged accounts, poor segmentation, missing monitoring, weak patch habits, or users being tricked into opening malicious content. Strong fundamentals make zero-day vulnerabilities harder to exploit and easier to contain.
Why zero-day risk is difficult to manage
Zero-day risk is difficult because defenders are working with incomplete information. A known security vulnerability can usually be ranked, assigned, patched, and verified against a documented fix. A zero-day may begin as a strange alert, a vendor advisory without complete details, unusual endpoint behavior, or threat intelligence that points to active exploitation but not a clean remediation path.
The uncertainty creates three operational challenges. First, teams must make decisions before all facts are available. Second, attackers may move quickly while defenders are still confirming scope. Third, normal patch management workflows may not fit because a patch may be unavailable, unstable, or difficult to deploy across critical systems.
The goal is not to eliminate all zero-day risk. No organization can promise that. The goal is to reduce the likelihood that a single unknown flaw becomes a major incident. That means building resilience into systems before the next disclosure, then using a calm, repeatable process when a credible threat appears.
A layered strategy for mitigation
The strongest approach combines prevention, detection, containment, and recovery. Relying on one control creates a brittle security model. For example, patching is essential, but patch management alone cannot protect against an exploit before a patch exists. Threat detection is essential, but detection without containment can leave attackers with time to spread.
A layered strategy should cover the full attack path:
- Asset visibility: Know which systems, applications, users, cloud workloads, and third-party tools exist in the environment.
- Exposure reduction: Remove unnecessary internet-facing services, disable unused features, and restrict administrative access.
- Hardening: Apply secure configurations, least privilege, application control, and strong authentication.
- Behavioral monitoring: Watch for suspicious activity rather than depending only on known malware signatures.
- Segmentation: Prevent one compromised system from becoming a path into the entire network.
- Rapid response: Prepare playbooks, decision rights, communications, and rollback plans before pressure is high.
- Recovery readiness: Maintain tested backups and restoration procedures for systems affected by malware attacks or destructive activity.
This layered model matters because zero-day vulnerabilities rarely cause damage in isolation. They become dangerous when an exploit connects to weak identity controls, excessive permissions, poor logging, or slow response.
Building an effective vulnerability management foundation
A mature vulnerability management program gives teams the visibility and discipline they need when unknown threats become known. It starts with an accurate inventory. If the security team cannot quickly answer where a vulnerable product is installed, who owns it, whether it is internet-facing, and what business process depends on it, response will be slower and riskier.
Good vulnerability management also requires prioritization. Not every issue carries the same urgency. A flaw in an exposed remote access system may require immediate action, while a vulnerability on an isolated test server may be handled through normal maintenance. Prioritization should consider exploitability, exposure, asset criticality, available controls, and evidence of active abuse.
Core elements of a strong program
- Comprehensive asset inventory: Include endpoints, servers, cloud services, SaaS integrations, network devices, containers, APIs, and operational technology where relevant.
- Ownership mapping: Assign accountable business and technical owners so remediation does not stall.
- Risk-based prioritization: Rank security vulnerabilities by real-world exposure and impact, not only by severity labels.
- Remediation tracking: Document exceptions, compensating controls, due dates, and validation results.
- Continuous scanning: Use authenticated scans, configuration checks, and cloud posture assessment where appropriate.
- Executive reporting: Translate technical risk into operational impact, trends, and decisions needed from leadership.
This foundation does not stop every zero-day. It does make the organization faster. When a vendor advisory appears, the team can identify affected systems, isolate high-risk assets, and coordinate patch management or temporary mitigations with less confusion.
Strengthening patch management without relying on patches alone
Patch management is one of the most important controls against known cyber threats, but zero-day mitigation requires a broader mindset. When patches are available, the organization needs a reliable way to test, deploy, verify, and document them. When patches are not available, teams need temporary controls that reduce exposure until a fix can be safely applied.
A practical patch process balances speed and stability. Critical systems may require testing, change windows, and rollback plans. However, overly slow approval processes can leave exploitable systems exposed. The best programs define emergency patch procedures in advance so urgent fixes do not get trapped in routine workflows.
When no patch is available
If a credible zero-day is being exploited and no fix exists, teams can still act. Temporary mitigations may include disabling a vulnerable feature, blocking affected ports, restricting access to trusted IP addresses, increasing authentication requirements, applying web application firewall rules, isolating systems, or taking a vulnerable service offline. The right action depends on business impact and threat likelihood.
Use a simple decision sequence:
- Identify exposure. Determine where the affected product or component exists and whether it is reachable by attackers.
- Assess criticality. Confirm what the system supports and what would happen if it were restricted or taken offline.
- Apply compensating controls. Reduce attack paths while waiting for a vendor fix or validated workaround.
- Increase monitoring. Add detections for suspicious processes, unusual authentication, command execution, data staging, or outbound traffic.
- Prepare the patch path. Test the vendor fix as soon as it is available, then prioritize deployment based on exposure.
- Validate closure. Confirm the patch or mitigation worked, and keep watching for signs of earlier compromise.
This approach keeps patch management central without pretending patches are always immediate or sufficient.
How can threat detection help when the vulnerability is unknown?
Threat detection helps by focusing on attacker behavior, not only on the exact vulnerability. Even if a security tool does not recognize a brand-new exploit, it may still detect suspicious actions that follow exploitation, such as privilege escalation, credential dumping, unusual scripting, lateral movement, unauthorized process spawning, or unexpected network connections. This is why behavioral analytics, endpoint telemetry, identity monitoring, and centralized logging are critical.
Signature-based tools still have value, especially once indicators are published, but they should not be the only line of defense. Zero-day activity often looks unfamiliar at the exploit stage and more recognizable during post-exploitation. Attackers usually need to execute commands, establish persistence, move through the environment, access data, or deploy malware. Monitoring those behaviors gives defenders more chances to interrupt the attack.
Effective threat detection should include:
- Endpoint detection and response: Monitor process behavior, file changes, memory activity, and suspicious execution chains.
- Network detection: Watch for command-and-control traffic, unusual outbound connections, scanning, and unexpected data movement.
- Identity monitoring: Alert on impossible travel, abnormal privilege use, new administrative accounts, and suspicious authentication patterns.
- Cloud logging: Review API calls, role changes, storage access, and unusual workload behavior.
- Email and web controls: Detect malicious attachments, credential harvesting, and suspicious links associated with malware attacks.
- SIEM or log correlation: Bring signals together so isolated alerts become a coherent investigation.
Detection should also be tuned to reduce noise. If analysts are overwhelmed by low-value alerts, they may miss the weak signals that reveal a zero-day campaign. Good detection engineering focuses on high-risk behaviors, context-rich alerts, and clear investigation steps.
Reducing exposure before attackers find it
Exposure management is the practical work of making systems harder to reach and exploit. It is especially important for internet-facing applications, VPNs, remote access tools, file transfer systems, identity platforms, and administrative interfaces. These assets are attractive because successful exploitation can provide an immediate foothold.
Begin by identifying what is externally visible. Compare security inventories with external attack surface data, DNS records, cloud accounts, and business-owned applications. Many organizations discover abandoned subdomains, forgotten test environments, old appliances, or third-party services that were never fully governed.
High-value exposure controls
- Remove unnecessary services: If a system does not need to be reachable from the internet, make it private.
- Limit access paths: Use VPN, zero trust access, allowlists, or identity-aware proxies for administrative services.
- Enforce multifactor authentication: Prioritize privileged accounts, remote access, cloud consoles, email, and developer tools.
- Harden configurations: Disable default accounts, unused protocols, legacy encryption, and unnecessary plugins.
- Separate environments: Keep production, development, and administrative networks logically distinct.
- Review third-party access: Confirm vendors and contractors have only the access they need, for only as long as they need it.
Reducing exposure has a simple benefit: attackers cannot exploit what they cannot reach. Even when a zero-day exists, strong access controls and segmentation can prevent broad compromise.
Containment and least privilege limit the blast radius
Assume compromise is a useful security mindset. It does not mean accepting failure; it means designing systems so one failure does not become a crisis. Least privilege, segmentation, and strong identity governance help contain zero-day exploitation by restricting what an attacker can do after gaining initial access.
Least privilege should apply to users, service accounts, applications, and machines. Administrative rights should be limited, time-bound where possible, and monitored closely. Service accounts should not have broad permissions simply because they are difficult to manage. Overprivileged identities often turn a single exploited server into a path toward sensitive data or domain-wide control.
Segmentation adds another boundary. A public-facing web application should not have unrestricted access to internal databases, identity systems, file shares, and management networks. Sensitive systems should require additional authentication, network rules, and monitoring. If attackers exploit an application, segmentation can slow them down and create detection opportunities.
Incident response for suspected zero-day exploitation
A suspected zero-day requires fast coordination, but panic creates mistakes. Incident response teams need a playbook that supports decisive action while preserving evidence and business continuity. The playbook should define who leads, who approves disruptive containment, who contacts vendors, who communicates with executives, and how legal or regulatory issues are escalated.
The first step is triage. Confirm what is known, what is suspected, and what systems may be affected. Do not wait for perfect certainty if there is credible evidence of active exploitation. Temporary containment can be appropriate while investigation continues.
Practical response checklist
- Open an incident channel with security, IT, application owners, legal, communications, and leadership as needed.
- Preserve evidence before wiping or rebuilding systems, especially logs, memory captures, disk images, and relevant configuration data.
- Identify affected assets using inventories, scans, endpoint telemetry, and cloud records.
- Contain high-risk systems by isolating hosts, restricting network paths, disabling vulnerable features, or rotating credentials.
- Hunt for related activity across endpoints, identities, network traffic, and cloud environments.
- Apply vendor guidance when available, but validate that mitigations are actually in place.
- Communicate clearly with stakeholders about business impact, risk, actions taken, and next decision points.
- Recover carefully by rebuilding compromised systems, patching, rotating secrets, and monitoring for recurrence.
After containment, conduct a lessons-learned review. The purpose is not blame. It is to improve logging, ownership, patch management, segmentation, and decision-making before the next event.
Security awareness and operational discipline matter
Not every zero-day begins with a dramatic server exploit. Some campaigns combine unknown vulnerabilities with social engineering, malicious documents, compromised websites, or credential theft. Users and administrators need practical guidance on reporting suspicious activity, handling unexpected prompts, and avoiding risky workarounds.
Security awareness should be specific rather than fear-based. Teach employees how to report unusual browser behavior, unexpected authentication requests, suspicious attachments, and system warnings. Train IT and help desk teams to recognize patterns that may indicate malware attacks or active exploitation. A quick report from a user can sometimes surface a broader issue before automated tools connect the dots.
Operational discipline also matters. Accurate documentation, clean change management, reliable backups, and tested recovery plans may not sound exciting, but they are essential during a zero-day event. When teams know where systems are, how they are configured, and how to restore them, response becomes more controlled.
How should organizations prioritize zero-day preparation?
Organizations should prioritize zero-day preparation by focusing first on the controls that reduce the greatest risk across the widest set of threats. Start with asset visibility, external exposure reduction, strong identity security, reliable patch management, endpoint detection, centralized logging, and tested incident response. These capabilities help against zero-day vulnerabilities, known security vulnerabilities, ransomware, account takeover, insider risk, and many other cyber threats.
A useful roadmap starts with realistic questions: Which systems would be most damaging if compromised? Which assets are exposed to the internet? Where do administrators have broad access? Which logs would investigators need during an incident? Which systems cannot be patched quickly, and what compensating controls protect them?
A practical priority model
- Know the environment. Build and maintain inventories for assets, software, identities, cloud resources, and data locations.
- Protect the perimeter and identity layer. Reduce exposed services, require strong authentication, and monitor privileged access.
- Improve detection coverage. Collect useful telemetry from endpoints, networks, cloud platforms, and identity systems.
- Formalize emergency change processes. Make it possible to apply urgent patches or mitigations without unnecessary delay.
- Segment critical systems. Limit lateral movement and isolate sensitive environments.
- Test response plans. Run tabletop exercises around zero-day scenarios, including no-patch situations.
- Review and improve. After exercises or real incidents, update playbooks, controls, and ownership records.
This model keeps the program practical. Instead of chasing every possible exploit, the organization builds durable capabilities that make many attack types less successful.
Common mistakes to avoid
Many organizations weaken their zero-day defenses through avoidable habits. One common mistake is treating vulnerability management as a scanning exercise rather than an operational process. A scan result has limited value if no one owns the asset, understands the risk, or has authority to fix it.
Another mistake is focusing only on prevention. Prevention is important, but zero-day attacks may bypass preventive controls. Without monitoring, response playbooks, and containment options, attackers can remain active longer than necessary.
Avoid these patterns:
- Waiting for a patch before taking any action when exposure can be reduced immediately.
- Ignoring end-of-life systems that cannot receive security updates but still support business processes.
- Giving service accounts excessive permissions because least privilege is inconvenient.
- Leaving logs decentralized or incomplete so investigations depend on guesswork.
- Using the same response plan for every incident instead of adapting to business criticality and threat severity.
- Failing to verify remediation after patches, configuration changes, or firewall rules are applied.
The best programs are not perfect. They are honest about gaps, fast at prioritizing, and disciplined about improvement.
Turning zero-day mitigation into a repeatable program
Mitigating zero-day vulnerabilities is not a single tool, checklist, or emergency meeting. It is an ongoing security practice that combines visibility, hardening, patch management, threat detection, containment, and recovery. The organizations that respond best are usually the ones that prepared before the advisory, exploit, or alert appeared.
Start with the basics that create the most leverage: know what you run, reduce what is exposed, secure identities, monitor behavior, patch quickly when possible, and document what to do when no patch exists. Then test the process with realistic scenarios. A well-practiced team can make calm decisions even when the details are incomplete.
Zero-day vulnerabilities will continue to appear because software and systems are complex. The defensible goal is resilience: making attacks harder to execute, easier to detect, smaller in impact, and faster to recover from. With a layered program and clear operational ownership, zero-day risk becomes manageable rather than mysterious.
